Choose what this site may store in your browser. You can change this at any time from the footer.

SRE AIOps services

Reliability, SLOs, incident intelligence, predictive operations and self-healing across hybrid environments.

Talk to a SRE AIOps Specialist
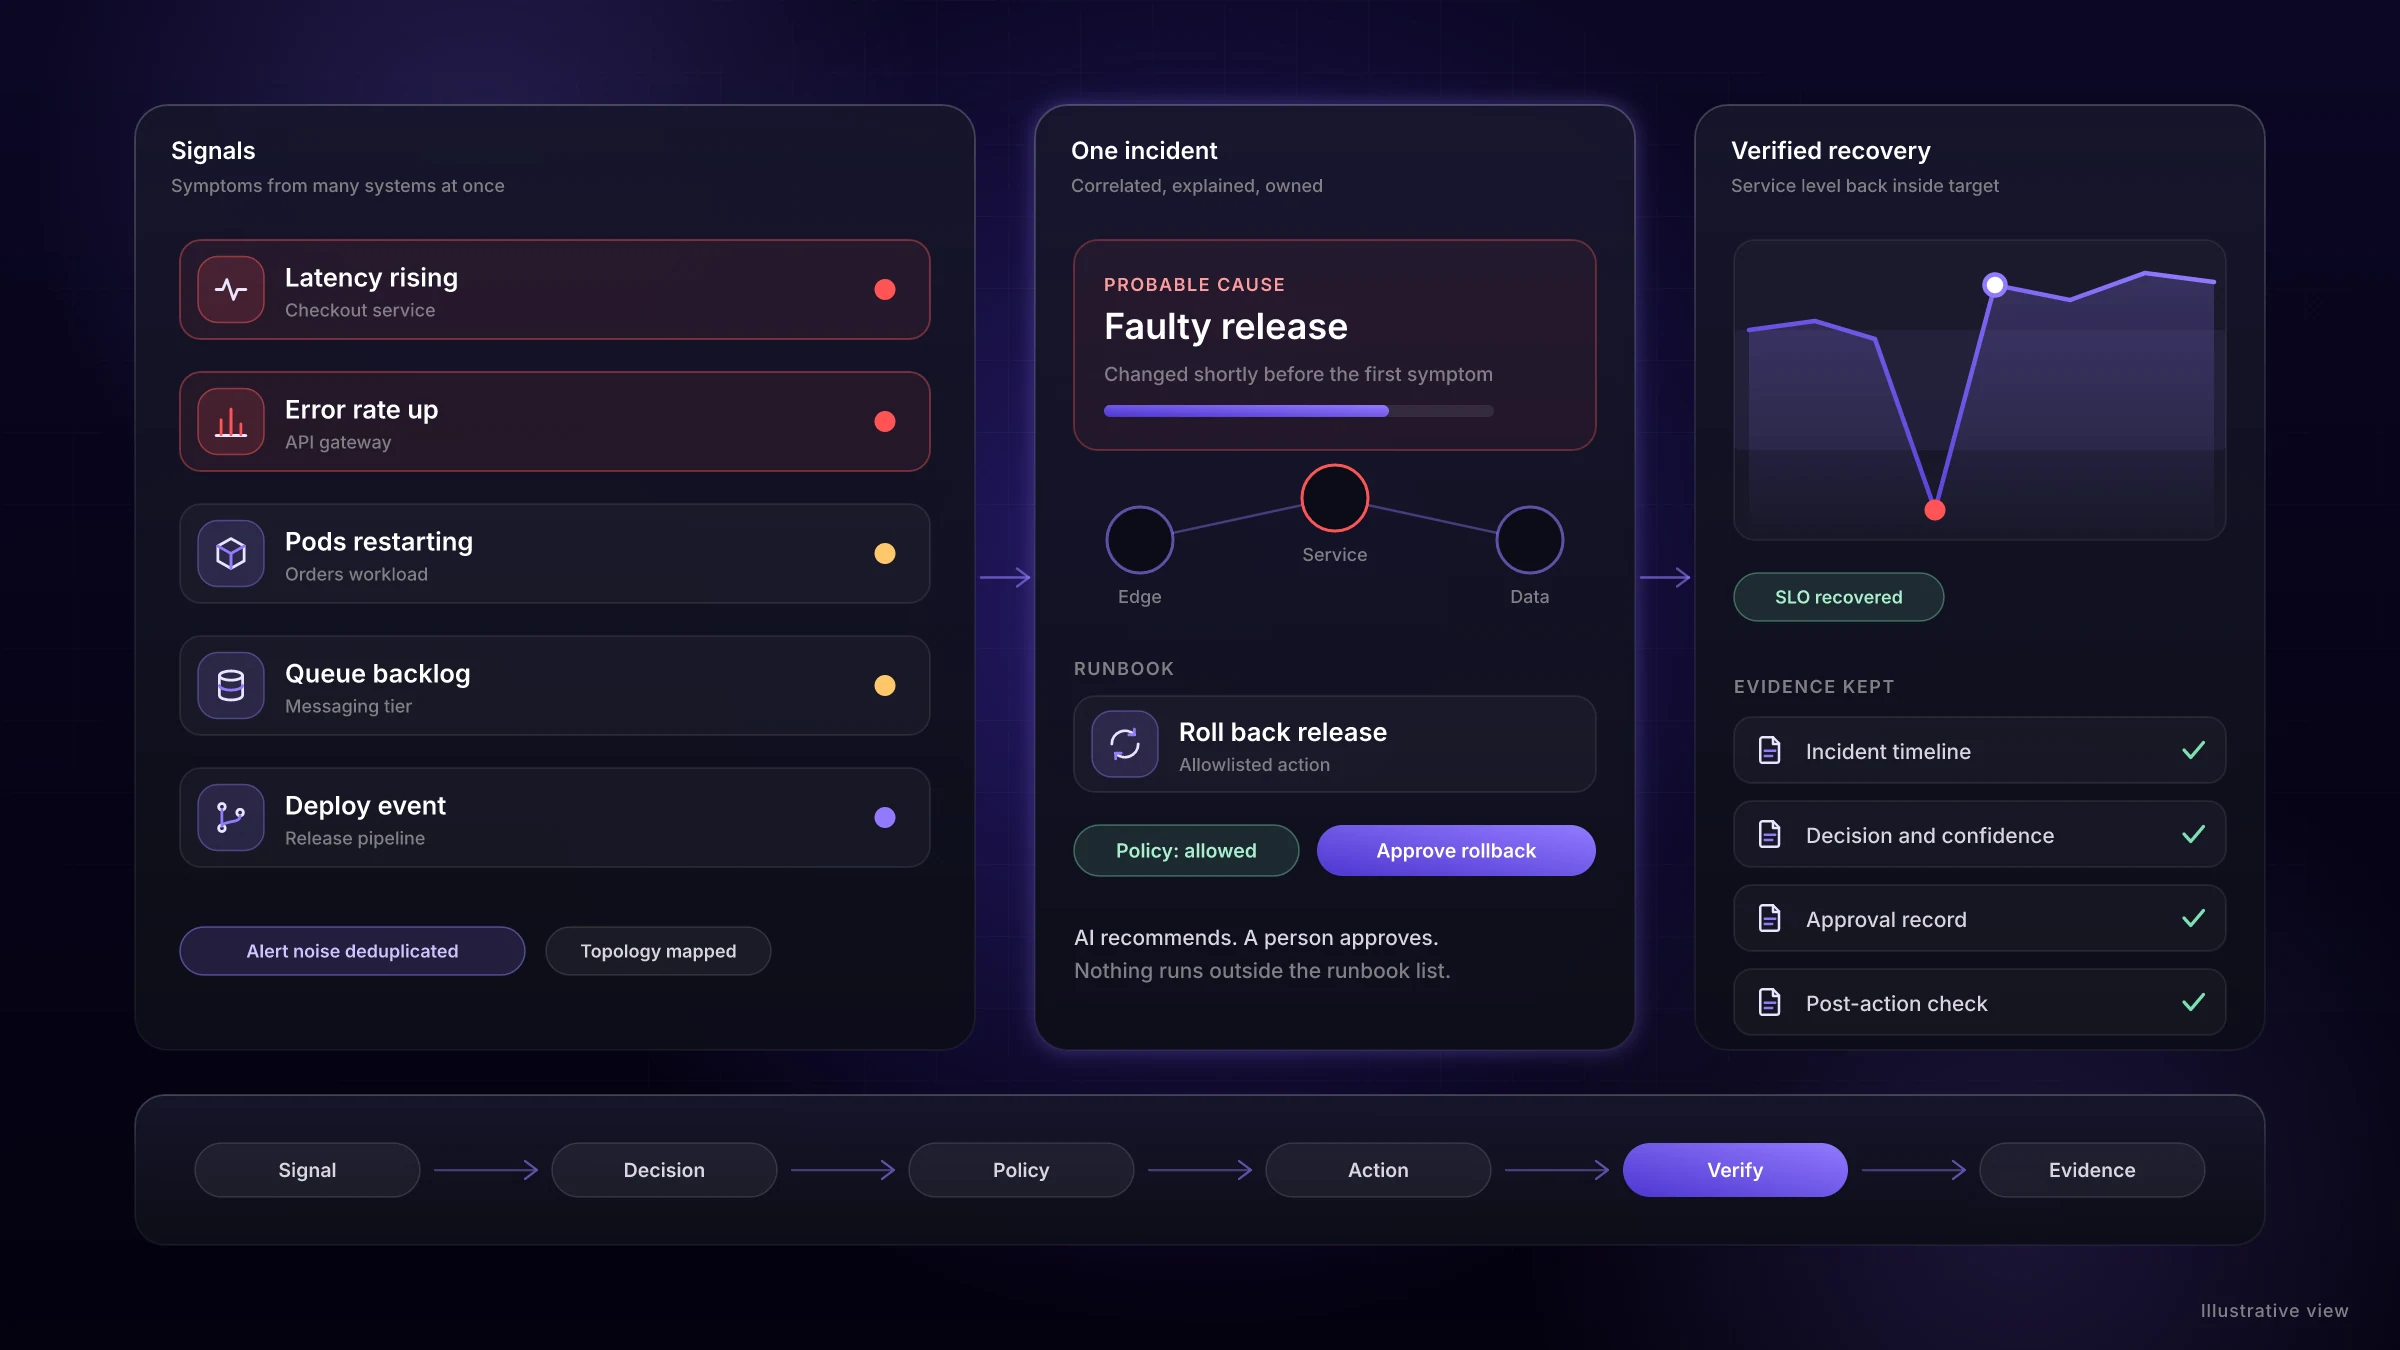
Illustrative view: alerts from many systems collapse into one incident with a probable cause, an approved rollback and a verified service-level recovery

Five SRE AIOps services

Each service can be taken alone. They share telemetry, policy and runbooks when combined.

Autonomous SRE & AIOps Command Center

Unify multi-site and cloud telemetry, correlate incidents, find probable root cause and coordinate safe remediation.

Example scenario

Inject a faulty release, correlate several symptoms into one incident, approve a rollback and verify SLO recovery.

Core capabilities

  • Telemetry normalization
  • Alert deduplication
  • Topology-aware root-cause analysis
  • SLO and error budget tracking
  • Incident timeline
  • Runbook automation

AI Self-Healing Infrastructure

Detect recurring failures and run policy-controlled remediation with verification.

Example scenario

Force a service failure, recommend a runbook, approve it, recover the service and show the evidence.

Core capabilities

  • Incident classification
  • Confidence and risk scoring
  • Runbook registry
  • Approvals
  • Pre- and post-checks
  • Rollback
  • Audit trail

Predictive SRE: Failure & Capacity Forecasting

Forecast capacity exhaustion and SLO risk before static thresholds are breached.

Example scenario

Simulate disk and traffic growth and alert before the real failure threshold is reached.

Core capabilities

  • Forecasting
  • Anomaly detection
  • Capacity runway
  • Error-budget projection
  • Predictive alerts
  • Model evaluation

ChangeGuard: Change Risk & Deployment Reliability

Score code, IaC and Kubernetes changes, control progressive delivery and roll back unhealthy releases.

Example scenario

Release a bad version, detect the canary regression and roll back automatically.

Core capabilities

  • Git and pull-request analysis
  • Terraform and Kubernetes diff
  • Explainable risk scores
  • Canary analysis
  • Change-to-incident correlation

Resilience, DR & Chaos Engineering

Prove DR readiness, backup restorability, failover and RTO/RPO through safe experiments.

Example scenario

Fail a primary site, recover to the secondary, validate the data and generate DR evidence.

Core capabilities

  • DR plan registry
  • Backup and restore validation
  • Chaos experiments
  • Failover and failback
  • RTO and RPO measurement
  • Evidence reporting

What you receive

Every service is built as a local-first lab, then extended to your private cloud and to AWS, Azure or GCP.

KPI dashboards

Ingestion health, processing latency, decisions, automation success and failure, overrides and false positives where measurable.

Runbooks and policies

Validated, allowlisted actions with approval rules and least-privilege identities.

Failure-path tests

Healthy, false-positive, policy-blocked, automation-failure, rollback and telemetry-source-failure cases, all exercised.

Audit evidence and demo

Retained evidence for every decision, a short demo script, and setup, troubleshooting and cleanup documentation.

Automation with guardrails, not blind trust

Rules every AIOps action follows, in every track.

Allowlisted actions only

AI output never goes straight to a shell, cloud API or cluster. It selects from validated runbooks.

Approval for high-risk change

Disruptive actions wait for a person. Low-risk, reversible steps can run on their own once you agree the rule.

Verified outcomes

Every action is followed by a health check, with rollback or compensation when the check fails.

Complete audit history

Signals, scores, model or rule versions, approvals and results are retained and reviewable.

Typical technology base

  • OpenTelemetry
  • Prometheus
  • Grafana
  • Loki / Tempo
  • Kubernetes
  • Helm
  • Terraform
  • Ansible
  • Argo CD / Rollouts
  • Python / FastAPI
  • PostgreSQL
  • Redis / NATS / Kafka
  • Trivy · Semgrep · Checkov

Adapted to the tools you already run.

Other AIOps tracks

Combine tracks to share telemetry, policy and runbooks.

Start with SRE AIOps?

Tell us what you run and where operations hurt most. We will suggest where to begin.

Talk to an AIOps Specialist

Stay in the loop

Blog posts, our newsletter and service updates on cloud migration, DevOps and reliability engineering, straight to your inbox.

We email you once to confirm. No spam, and we never share your address. Privacy Policy